AI Agent Rate Limiting: Prevent API Overload and Runaway Traffic
AI agent rate limiting, concurrency caps, and sandboxing can prevent API overload. Learn practical controls for safer, more reliable automation.
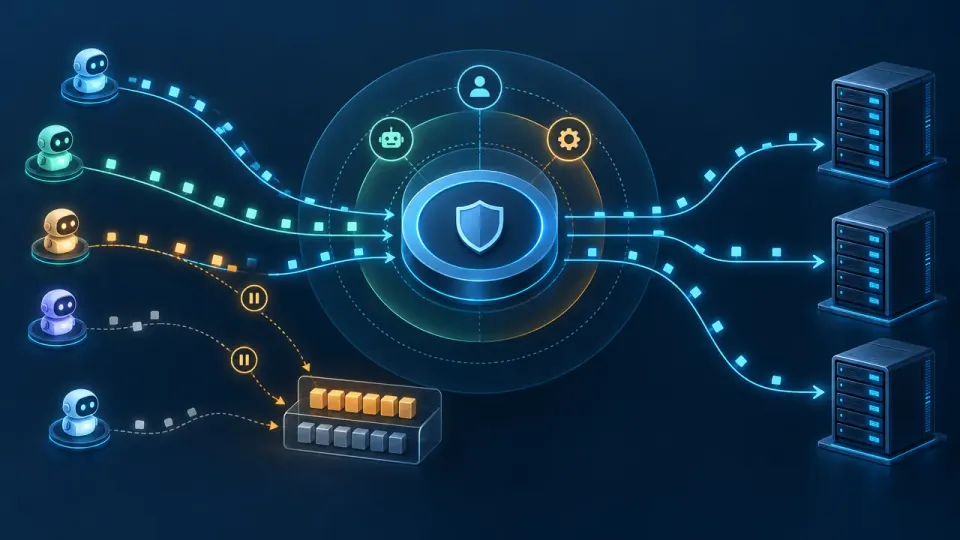
Table of Contents
Quick Answer
Prevent AI agents from overloading websites and APIs by assigning each workflow a distinct identity and combining request-rate limits with concurrency caps, timeouts, and operation quotas. Restrict agent permissions, bound retries and resource use, require approval for risky actions, and monitor each agent so you can pause it quickly.
Recent reporting has highlighted concerns about autonomous agents interacting with external systems and the risks of granting them broad access. The practical lesson is to plan for mistakes and unexpected behavior: give every agent a clear identity, cap what it can consume, and make it possible to pause its actions.
Why AI agents need limits beyond ordinary per-user throttling
A human user usually sends requests in response to a visible action. An agent may call several tools for one task, make parallel requests, or repeat an operation when a response is slow. Multiple agents may also share one user account or API key, hiding which workflow is generating traffic.
A per-user limit alone may therefore miss important patterns. It can block legitimate activity from a busy user while failing to distinguish a runaway agent from other requests under a shared identity. Use distinct identities for agents and workflows so limits and investigations can target the source of traffic.
Rate limiting is not a substitute for authentication or authorization. It controls how much traffic reaches a service; it does not determine whether an agent should be allowed to access a particular record or perform a sensitive action.
Set layered limits for each agent and API
Apply limits at several levels, rather than relying on one global threshold:
- Per agent identity: Cap requests from a particular agent or workflow.
- Per user and API key: Keep an individual user or credential from consuming a disproportionate share of capacity.
- Per endpoint: Set tighter limits for expensive operations, such as generating reports or running searches.
- Per organization: Prevent the combined activity of many agents from exceeding an overall allocation.
Tune limits to real service capacity and normal usage. A simple read request and a complex data export should not necessarily have the same quota. Consider separate limits for short bursts and sustained traffic, and make sure shared limits account for parallel workers.
Set quotas for costly operations as well. For example, an agent might be allowed a certain number of ordinary lookups per minute but only a few large exports per hour. Where appropriate, set an execution or spending budget for the workflow. When a limit is reached, return a clear response the agent can handle rather than letting work pile up invisibly.
Make throttling and retries safe
When an API returns HTTP 429, the client should treat it as a signal to slow down, not as a reason to immediately repeat the request. If the response includes a Retry-After instruction, wait for the specified interval before retrying.
If no retry interval is provided, use bounded exponential backoff with jitter : increase the wait after each failed attempt, add a random delay to spread out clients, and stop after a small, configured number of retries. For example, an agent could wait about one second after the first throttle response, then two seconds, then four - with some random variation - before giving up. Set an overall deadline so retries cannot outlive the task.
Do not retry every failure in the same way. A temporary network error may be retryable; a validation error usually is not. Retrying an operation that creates a payment, account, or order can also duplicate its effect. Use idempotency keys or another deduplication method for operations that may be repeated safely.
Limit resource use inside each request
A low request rate can still permit a single request to consume excessive resources. Add application-level controls such as:
- Maximum request and upload sizes.
- Pagination limits and maximum page sizes.
- Bounds on query complexity, records returned, or processing time.
- Quotas for costly operations and generated outputs.
- Limits on the number of tools or steps an agent can use in one task.
These controls complement infrastructure throttles. Monitor usage patterns so you can spot an agent repeatedly requesting large pages, running expensive searches, or consuming an unusual amount of compute. Log enough detail to attribute usage to an agent without exposing secrets in logs.
Sandbox agent access and require approval for risky actions
Rate limits cannot prevent an agent from using its permitted access in the wrong way. Give each agent narrowly scoped credentials, and grant only the actions and data its task requires. Avoid shared, long-lived credentials where possible, and make them revocable.
For browser automation or code execution, restrict filesystem and network access. Use explicit allowlists for permitted destinations and tools, rather than allowing an agent to reach arbitrary services. Keep untrusted input separate from instructions that authorize actions, and do not assume a model will reliably distinguish the two.
Separate the agent's ability to propose an action from its authority to execute it. Require a person to approve high-impact actions such as sending external messages, changing access permissions, deleting data, or making purchases. Use dry-run modes to show what a workflow would do before it makes changes. Provide a kill switch that can stop the agent and revoke its credentials quickly.
Monitor, test, and tune controls before agents reach production
Track requests, latency, errors, throttles, retries, and resource use by agent and workflow. Alerts should catch sudden traffic increases, repeated 429 responses, retry spikes, and unexpected cost growth. Make sure operators can identify the responsible agent and pause it without disrupting unrelated users.
Test limits under realistic conditions. Simulate bursts, slow responses, failures, and concurrent agent runs. Confirm that clients honor Retry-After , stop at their retry cap, and do not duplicate non-idempotent actions. Tune thresholds against normal traffic and service capacity, then revisit them as workloads change.
Implementation checklist:
Audit one agent workflow this week: give it a distinct identity, set request and concurrency limits, cap retries and execution budgets, and test that you can pause it safely. Rate limiting reduces overload risk, but it does not replace authentication, authorization, sandboxing, or monitoring.
Step-by-Step Guide
Assign each agent a distinct identity
Give every agent or workflow its own identifiable credentials where possible. Use those identities in limits, logs, alerts, and controls so you can isolate a noisy workflow without affecting unrelated users.
Set layered traffic and workload limits
Configure request-rate limits per agent, user, endpoint, and organization. Add concurrency caps, timeouts, and separate quotas for expensive operations such as exports.
Bound retries and resource consumption
Honor Retry-After responses, use bounded exponential backoff with jitter when no interval is provided, and set a retry cap and overall deadline. Also restrict payload sizes, page sizes, query complexity, and execution time.
Restrict credentials, tools, and network access
Grant only the data and actions required for the task. Use revocable credentials and explicit tool and destination allowlists, especially for browser automation and code execution.
Add approval gates for high-impact actions
Separate an agent's ability to propose an action from its authority to execute it. Require human approval for actions such as deleting data, changing permissions, making purchases, or sending external messages, and provide a kill switch.
Monitor and test agent behavior
Track requests, latency, errors, throttles, retries, and resource use by agent. Test bursts, slow responses, failures, and concurrent runs, then confirm that limits work and the agent can be paused safely.
Key Statistics
- HTTP 429 is the standardized status code for 'Too Many Requests.'RFC 6585, Section 4, defines status code 429 for rate limiting and notes that a response may include a Retry-After header.
- Retry-After can specify a wait as either a delay in seconds or an HTTP date.RFC 9110 defines the Retry-After response field. The article recommends honoring the server's instruction before retrying a throttled request.
- The article's illustrative backoff sequence increases waits from about 1 second to 2 seconds to 4 seconds, with random variation.This is an example from the article, not a universal benchmark or recommended fixed schedule; retry delays and caps should be configured for the service and workflow.
Frequently Asked Questions
Why do AI agents need rate limits?
How should an AI agent handle an HTTP 429 response?
What limits should I use to prevent an AI agent from overloading an API?
How do you safely sandbox an AI agent?
Key Takeaways
- Use distinct identities for agents and workflows so you can apply limits and trace traffic to its source.
- Layer per-agent, per-user, per-endpoint, and organization-wide rate limits with concurrency caps, timeouts, and quotas for costly operations.
- Handle HTTP 429 responses by honoring Retry-After or using bounded exponential backoff with jitter, and stop after a configured retry limit.
- Limit payload sizes, pagination, query complexity, execution time, and tool use because a single request can still consume excessive resources.
- Scope credentials and network access, require approval for high-impact actions, and provide monitoring and a kill switch.