AI Agents Improve Without Retraining With ScholarEvolve
AI agents can improve without retraining: ScholarEvolve raised Qwen3.5-27B task completion on AppWorld from 69.0% to 81.4%.
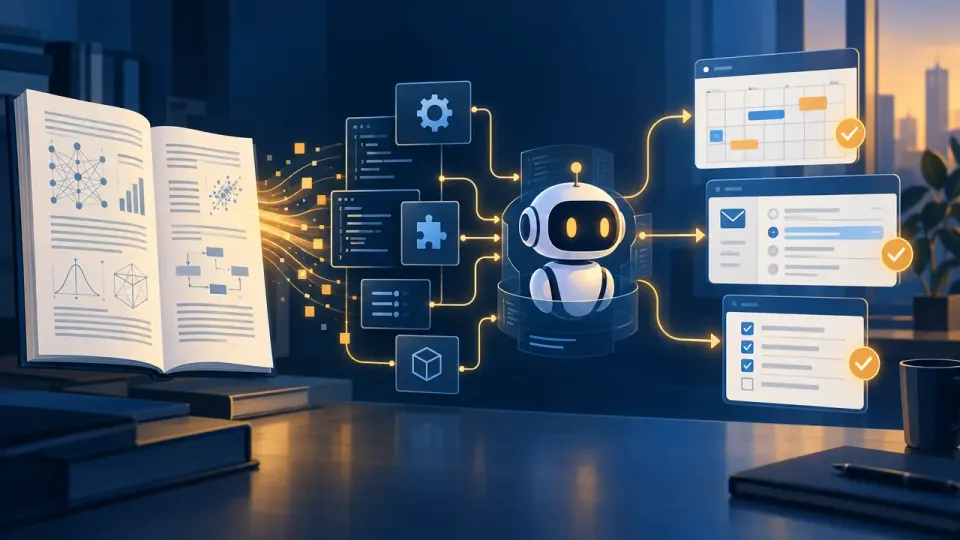
Table of Contents
Quick Answer
ScholarEvolve improves AI agent performance by turning techniques from academic papers into software upgrades for the agent harness, without retraining the underlying model. On AppWorld Normal, the researchers reported that Qwen3.5-27B task completion rose from 69.0% to 81.4%.
The result highlights a part of agent performance that can be overlooked: an AI agent depends not only on the model generating responses, but also on the software harness that manages its instructions, context, tools, and errors.
ScholarEvolve raised Qwen3.5-27B task completion on AppWorld
On the AppWorld Normal benchmark, Qwen3.5-27B completed 69.0% of tasks with its existing setup. After ScholarEvolve improved the agent harness, its task completion rate rose to 81.4%. The researchers reported that the gain closed about 74% of the performance gap with GPT-5.4 on the benchmark.
The change was to the system around the model, not the model itself. That distinction matters for teams deciding how to improve AI agents: retraining or fine-tuning can be costly, while harness changes may address practical problems in how an agent uses its existing capabilities. The benchmark result is specific to the reported setup, however, and does not establish that every model or task will see a similar improvement.
The framework turns research techniques into agent harness upgrades
ScholarEvolve is designed to translate ideas from research papers into code changes to an AI agent harness. Rather than relying only on developers to manually find and implement relevant techniques, the framework uses research methods as a source of potential software improvements.
Those improvements target the operational layer around the model. Examples include formatting outputs so they follow the expected structure, managing a limited context budget, and recovering when an API call produces an error traceback. Each issue can disrupt a multi-step task even when the model can reason about what to do next. A better harness can help the agent preserve useful information, communicate with tools in the required format, and respond constructively to failures.
This is a different route to better AI agent performance than changing model weights. Other work on agent self-improvement has explored recursive changes to agent software and, in some cases, model weights. ScholarEvolve’s reported result is notable because the improvement came through harness evolution without a model update.
Better harnesses help, but do not replace safeguards
A stronger harness is not a fix for every weakness in an agent system. It cannot by itself make an unreliable model consistently capable, repair a weak retrieval pipeline, or replace deterministic policy guardrails at an API gateway. Those controls serve different purposes: harness logic helps an agent manage tasks, while gateway rules can enforce limits on what requests are allowed.
For developers, the practical takeaway is to inspect the whole agent stack before assuming that a performance problem requires retraining. Check whether the system handles context limits, formats tool outputs reliably, and recovers from API errors. These are concrete areas where software improvements may help - while model capability, retrieval quality, and safety controls still need to be evaluated separately.
Step-by-Step Guide
Audit the agent stack
Review the model, harness, retrieval pipeline, tools, and safety controls separately to identify where task failures originate.
Find harness failure points
Check whether context limits, tool-output formatting, or API errors are disrupting multi-step tasks.
Apply targeted harness upgrades
Use relevant research techniques to improve context handling, enforce expected output formats, or recover from tool errors.
Benchmark the unchanged model
Run the same tasks before and after the harness changes while keeping model weights and evaluation conditions fixed.
Validate safeguards independently
Test model capability, retrieval quality, and API gateway policies separately; do not treat harness improvements as replacements for these controls.
Key Statistics
- Qwen3.5-27B completed 69.0% of tasks before the harness improvement and 81.4% afterward.Reported by researchers from the University of California, Santa Barbara, and Microsoft for Qwen3.5-27B on the AppWorld Normal benchmark using ScholarEvolve.
- The reported improvement closed about 74% of the performance gap with GPT-5.4.The researchers reported this comparison for the AppWorld Normal benchmark; it describes the tested setup and should not be generalized to other tasks or models.
- The task-completion increase was 12.4 percentage points, from 69.0% to 81.4%.Calculated from the baseline and post-improvement rates reported by the researchers for Qwen3.5-27B on AppWorld Normal. The model was not retrained and its weights were not changed.
Frequently Asked Questions
What is ScholarEvolve?
How did ScholarEvolve improve AI agent performance?
How much did Qwen3.5-27B improve on AppWorld?
Can an AI agent harness replace model retraining or safety guardrails?
Key Takeaways
- ScholarEvolve translates research techniques into code changes for an AI agent's software harness.
- The framework targets operational issues such as output formatting, context management, and API error recovery.
- On AppWorld Normal, Qwen3.5-27B task completion increased from 69.0% to 81.4% in the reported setup.
- The improvement came without retraining the model or changing its weights.
- Harness improvements complement, but do not replace, model evaluation, retrieval quality checks, or safety guardrails.