AI Coding Agent Harness Cost: Measure Overhead and ROI
Measure AI coding agent harness cost against task success, API spend, and shipped PRs with a practical benchmark for choosing tooling that earns its overhead.
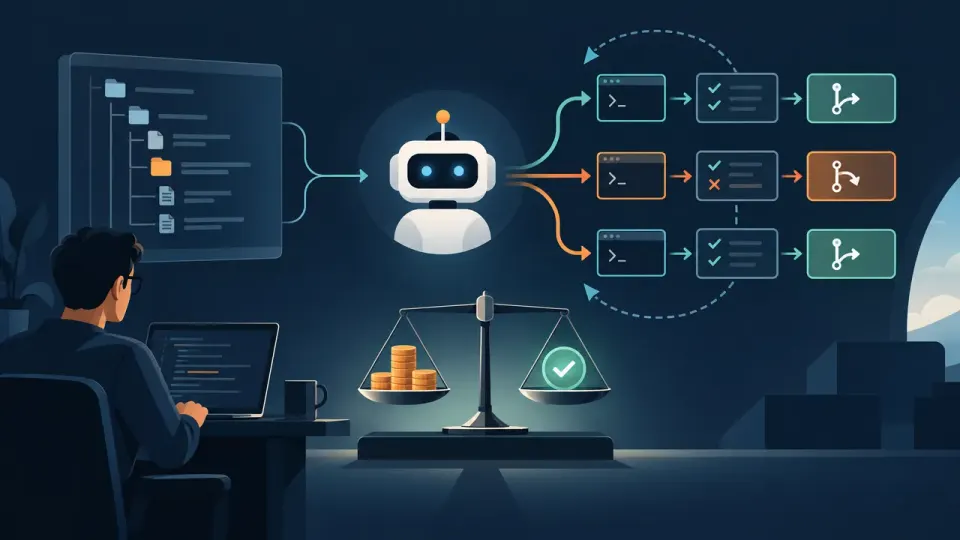
Table of Contents
Quick Answer
Measure AI coding agent harness cost by comparing total model, tool, and compute spend with successful tasks and shipped pull requests on the same representative workload. Keep added overhead only when repeatable results show that its accuracy, recovery, or delivery benefits justify the extra cost.
The useful question is not whether a harness uses more tokens. It is whether the complete model-and-harness setup delivers successful coding work at a worthwhile cost. Measure that on your own tasks before standardizing a configuration.
What counts as harness cost beyond the model bill?
The model bill usually reflects input and output tokens, sometimes at different rates. Harness overhead is the additional usage caused by the agent’s operating loop. Depending on the system, this may include:
- System instructions, tool definitions, and repository context repeated across calls.
- Intermediate reasoning or planning text sent to the model.
- Additional model turns for tool selection, code inspection, test execution, or revisions.
- Retry and recovery cycles when a command fails or an initial solution does not work.
Not every harness exposes these items separately. Some costs may be included in the model’s reported token usage, while other expenses, such as compute or tool services, are billed separately. For a fair comparison, measure the total cost of operating each configuration, not just the headline price of its model.
Keep model usage and other operating costs distinct in your records where possible. That makes it easier to see whether a more expensive run is due to the model, the harness’s extra turns, or external tools.
Why higher spend does not automatically mean higher accuracy
More steps can give an agent additional chances to inspect code, run tests, and correct mistakes. But extra interaction is not inherently useful. A harness may repeat context, ask for unnecessary intermediate work, or retry without improving the final result.
A reported study found that a coding-agent harness could nearly triple cost without improving task accuracy. The takeaway is not that harnesses are wasteful. It is that additional spend should be validated against outcomes rather than assumed to create them.
The reverse is also possible: harness design can make a model more capable on a particular task. For example, the ScholarEvolve system was reported to improve benchmark performance, including a 14-point gain for Qwen3.5-27B on AppWorld. These findings point to the same practical lesson: overhead has to be judged in context. Neither “more harness” nor “less harness” is a reliable rule by itself.
Benchmark the full model-and-harness configuration
Treat each configuration as a package: model, harness, tool access, instructions, and reasoning settings. A change in any of these can affect both cost and results. Reported effects of adjusting thinking budgets varied across model-harness pairings, so results from one stack may not transfer to another.
For each run, record:
Run each configuration on the same tasks. If results vary between runs, repeat enough tests to avoid making a decision based on one lucky or unlucky attempt. Keep the evaluation method stable; changing the test set or success criteria halfway through makes the comparison harder to trust.
Cost per successful task = total evaluation cost ÷ successful tasks
For example, if a configuration costs $100 across 50 attempts and succeeds on 25, its cost per successful task is $4. If another costs $150 and succeeds on 45, its corresponding cost is about $3.33. The second setup costs more overall, but less for each success. The example is illustrative; use your actual workload and costs.
Also report the success rate separately. A team may accept a higher cost per success when the work is especially valuable or failure is expensive. Showing both figures makes that trade-off visible instead of hiding it behind a single average.
Connect coding-task results to shipped PRs and business value
Benchmark success is a useful early signal, but a passed task is not automatically a merged change. Track how many agent-assisted changes become reviewed, accepted, and shipped pull requests. Include human review and rework where they materially affect the cost or time saved.
A panel discussion illustrated this framing by translating a $600 daily bill into roughly $30 per PR. That arithmetic only helps if the PRs are useful and shipped; spend without delivered work is not a return. Your team should calculate its own cost per shipped PR and consider whether the changes reduce effort, shorten delivery time, or improve throughput.
When is a more expensive harness worth keeping?
Keep the added overhead when repeatable evidence shows it produces enough value: more successful tasks, better recovery from errors, or more useful PRs reaching production. A higher price may be reasonable if it reduces expensive failures or saves substantial engineering time.
If the more expensive setup costs more but does not improve outcomes that matter to your team, test leaner settings. Change one part of the configuration at a time where practical, then rerun the same benchmark. This helps identify whether a particular tool, instruction set, or reasoning budget is earning its cost.
Run a controlled benchmark on a representative set of your team’s coding tasks. Compare each configuration’s total cost with its successful tasks and shipped PRs, then keep the harness settings that deliver enough measurable value to justify their overhead.
Step-by-Step Guide
Build a representative task set
Select real coding work across task types and sizes, such as bug fixes, small features, and test updates. Keep task descriptions, repository state, tool permissions, and completion criteria consistent across configurations.
Record full configuration costs
For each run, log input and output tokens, model-call counts, model API charges, relevant tool or compute fees, retries, and completion time.
Score task outcomes consistently
Apply the same pass/fail rubric to every run. Check whether the requested change is correct and whether it passes tests without introducing regressions.
Calculate cost per successful task
Divide total evaluation spend by successful tasks, and report the success rate separately. Repeat variable runs enough to avoid relying on a single lucky or unlucky result.
Validate value against shipped work
Track which agent-assisted changes are reviewed, accepted, and shipped. Include relevant review and rework costs, then compare cost per shipped PR and the engineering value delivered.
Key Statistics
- One reported study found that a coding-agent harness could nearly triple cost without improving task accuracy.The article reports this study result but does not identify the study by name, so treat it as a reported finding rather than a universal benchmark.
- ScholarEvolve was reported to produce a 14-point performance gain for Qwen3.5-27B on AppWorld.This is a reported benchmark result cited in the article to illustrate that harness effects can vary by model and task.
- In the article's illustrative example, $100 across 50 attempts with 25 successes equals $4 per successful task; $150 across 50 attempts with 45 successes is about $3.33.These figures are arithmetic examples, not observed benchmark data. Teams should substitute their measured workload costs and outcomes.
- A panel discussion framed a $600 daily bill as roughly $30 per PR.The article presents this as an illustrative panel-discussion calculation and cautions that the PRs must be useful and shipped for the figure to indicate value.
Frequently Asked Questions
How do you calculate AI coding agent cost per successful task?
Does a more expensive coding-agent harness improve accuracy?
What costs should you include when measuring harness overhead?
How can you tell whether an AI coding harness is worth keeping?
Key Takeaways
- Harness overhead can include repeated context, extra model calls, retries, and tool or compute charges.
- Higher token use or spend does not guarantee better coding accuracy.
- Compare complete model-and-harness configurations on the same tasks, repository state, permissions, and success criteria.
- Track both success rate and cost per successful task, calculated as total evaluation cost divided by successful tasks.
- Validate benchmark results against reviewed and shipped pull requests, including material human review and rework costs.