
AI Decision Models: Validate Outputs and Build Trust
Learn how to use AI decision models safely with business context, trusted-data validation, production monitoring, and clear human-review limits.
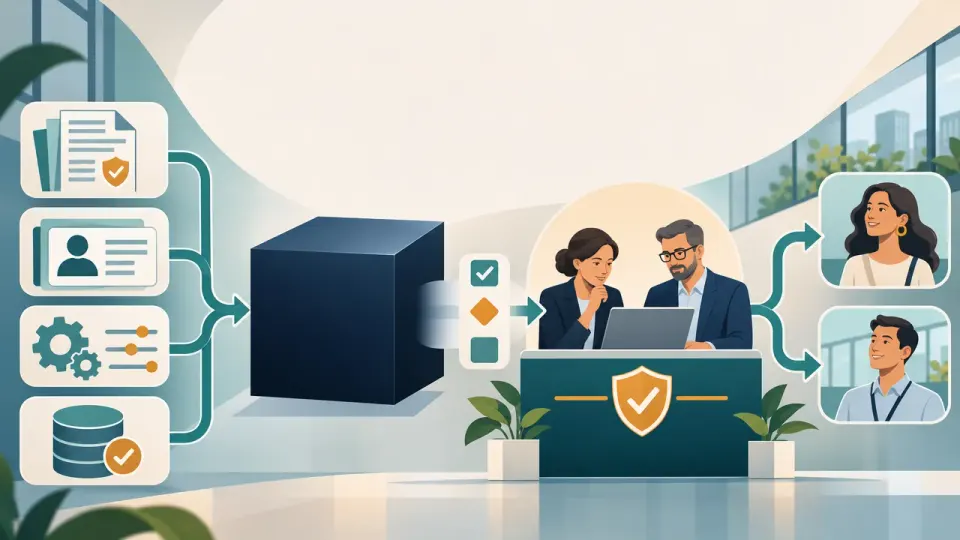
Table of Contents
Quick Answer
Use AI decision models by supplying current business context, testing their outputs against trusted data, and monitoring results in production. Set autonomy according to the risk of an error, with human review for uncertain or high-impact decisions.
Treat these models as components in a decision process, not as authorities. A useful operating pattern is to define the business context, validate outputs against evidence, then limit the model’s autonomy according to the risk of getting a decision wrong.
Why opaque AI decisions put more responsibility on your team
A model may produce a structured answer such as “approve,” “review,” or “reject” without revealing the steps behind it. In some systems, the explanation is not available or is not a reliable account of how the output was produced. Asking the model to explain itself does not necessarily provide a dependable audit trail.
That shifts the focus from inspecting an answer’s internal reasoning to testing whether it is appropriate for the task. Can the model use the relevant policy? Does it have current information? Does it respect operational limits? Would it make the same decision for a similar case?
Before deployment, define the decision the model is allowed to make, the evidence it should use, and the consequences of an incorrect output. A system that suggests a product category may need fewer controls than one that changes a customer’s credit limit or blocks a payment.
Give the model business context before it makes a decision
AI context design is more than writing a detailed prompt. It means giving the model the specific information and rules needed to make a decision inside your organization’s workflow. If a model lacks a key constraint, it may return a fluent answer that is still operationally wrong.
- Policies and business rules: Eligibility criteria, approval thresholds, exceptions, and prohibited actions.
- Standard procedures: The steps employees follow, including when to verify information or escalate a case.
- Customer requirements: Contract terms, service preferences, or account-specific instructions that affect the decision.
- Historical information: Relevant prior cases and their outcomes, while avoiding outdated examples that conflict with current policy.
- Operating constraints: Inventory, capacity, delivery windows, legal limits, or other conditions that determine what actions are possible.
For example, a delivery-planning model should not recommend a shipment based only on the destination and requested date. It may also need current capacity, service commitments, inventory status, and rules for handling late or restricted shipments. Context should be current, clearly prioritized, and limited to what is relevant. If sources conflict, specify which source takes precedence.
Validate decisions against trusted data before deployment
Do not assess a model only by whether its answers sound plausible. Compare decisions with trusted sources and known outcomes. For a customer-support model, that might mean checking whether its proposed refund matches the current policy and the customer’s transaction record. For a risk workflow, it might mean verifying that required evidence is present before an action is allowed.
Build a test set from representative cases, including routine examples and difficult edge cases. Run offline simulations to see how the model performs across normal and unusual conditions. Synthetic tests can help explore rare situations - for instance, conflicting account details or a request that falls just outside an eligibility threshold - but they should supplement, not replace, examples grounded in real operations.
Use both automated and human evaluation. Automated checks can test fields, policy limits, and agreement with trusted data. Reviewers can assess whether outputs are useful, whether important exceptions are missed, and whether the system handles ambiguous cases appropriately. Record the expected answer, the model’s output, the reason for any failure, and whether the context or workflow needs to change.
Set acceptance criteria before testing. These might include a minimum accuracy on high-priority cases, no violations of specified business rules, and a defined rate of escalation for ambiguous inputs. A single overall accuracy figure can hide costly failures in a smaller, higher-risk category.
What PayPal’s accuracy gains show about context and validation
PayPal reported raising the accuracy of an AI assistant from 43% to 95% without changing the underlying model. The reported improvement came from changes around the model, including the use of certified data, standard operating procedures, policies, risk checks, and human verification.
The example illustrates why model choice is only one part of decision quality. Better data and clearer rules can make an existing model more useful in a specific workflow. But the result is not a guarantee that another organization will achieve the same improvement. Accuracy depends on the task, the evaluation method, the data, and what counts as a correct answer. Treat reported gains as a reason to test context and process changes, not as a forecast for your own system.
Monitor production decisions and set limits on autonomy
Pre-deployment tests cannot capture every change in real-world inputs. Monitor production decisions for error rates, policy violations, unusual output patterns, escalation volume, and changes in the types of cases the model receives. Review a sample of accepted outputs as well as flagged ones; otherwise, silent errors can go unnoticed.
Create a feedback loop so that reviewers can label errors, identify missing context, and send findings to the team responsible for the model and workflow. Re-test after policy updates, data changes, or changes to the model. Do not rely on employees to notice poor outputs while handling their normal workload. Make review an explicit task, with clear ownership and a way to report problems.
- Automatically complete routine, low-risk cases that pass validation checks.
- Send uncertain cases, unusual inputs, or decisions with meaningful customer impact to a trained reviewer.
- Escalate cases involving conflicting evidence, policy exceptions, or high potential harm to a designated decision-maker.
Confidence scores can help with routing, but they are not proof that an answer is correct. Pair them with risk rules, input checks, and observed performance. Keep a person responsible for decisions where errors are costly or difficult to reverse, and make it possible to pause or roll back automation when monitoring finds a problem.
Choose one AI decision workflow to assess. Document the context it needs, test its outputs against trusted examples, and define when it must pause for human review before expanding its autonomy.
Step-by-Step Guide
Define the decision and its risks
Specify what the model may decide, what evidence it must use, and the likely consequences of an incorrect output. Set limits that reflect the cost and reversibility of errors.
Provide current business context
Give the model relevant policies, procedures, customer requirements, historical information, and operational constraints. Identify which source takes precedence if information conflicts.
Build a representative test set
Include routine cases, edge cases, ambiguous inputs, and examples tied to trusted operational outcomes. Use synthetic cases to explore rare scenarios, but do not rely on them instead of real examples.
Evaluate outputs against acceptance criteria
Run automated checks for required fields, policy limits, and agreement with trusted data, then have reviewers assess exceptions and usefulness. Record expected answers, failures, and any context or workflow changes needed.
Monitor results and route decisions by risk
Track errors, policy violations, unusual output patterns, and escalation rates in production. Automate validated low-risk cases, send uncertain or consequential decisions to reviewers, and define how to pause or roll back automation.
Key Statistics
- PayPal reported that an AI assistant's accuracy rose from 43% to 95%.The article attributes the reported improvement to changes around the model, including certified data, standard operating procedures, policies, risk checks, and human verification. It does not provide the evaluation method or guarantee that other organizations will achieve the same result.
- The reported change from 43% to 95% is a gain of 52 percentage points.This is calculated from the two figures PayPal reported in the article. It describes that specific assistant and should not be treated as a general benchmark for AI decision systems.
Frequently Asked Questions
Can you trust an AI decision model that does not explain its answers?
What context should you give an AI decision model?
How do you validate AI decision model outputs?
When should a human review an AI decision?
Key Takeaways
- Treat an AI model as one component in a decision process, not as the final authority.
- Provide relevant policies, procedures, customer requirements, historical information, and operating constraints.
- Test outputs against trusted examples, including routine cases and difficult edge cases.
- Monitor production decisions and re-test after policy, data, or model changes.
- Automate low-risk decisions selectively and route uncertain or high-impact cases to human reviewers.