How LLMs Think: Play a Game to Spot ChatGPT Hallucinations
Learn how LLMs generate text with a quick “Be the LLM” game, then use practical checks to spot unsupported ChatGPT answers.
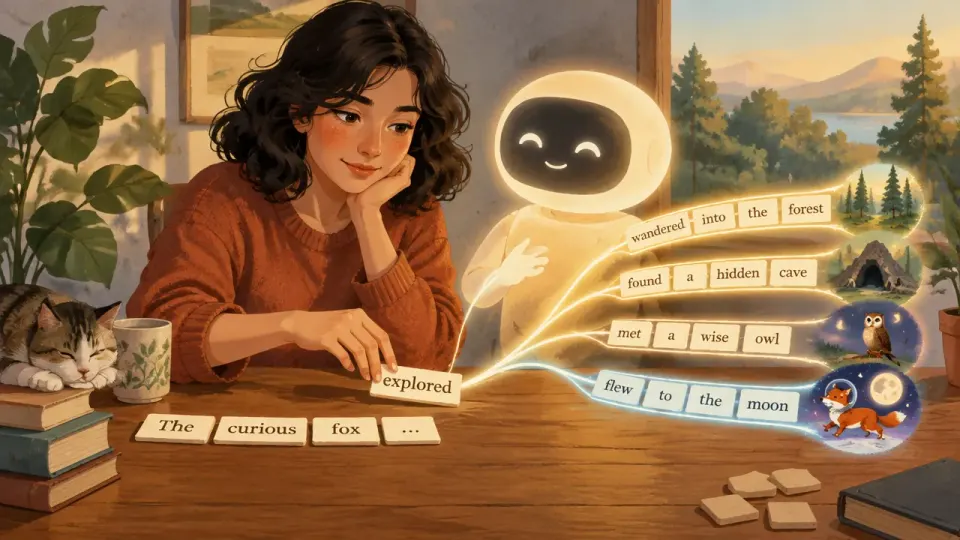
Table of Contents
Quick Answer
LLMs generate text by predicting likely next tokens from the prompt and the text generated so far. Because a fluent, plausible continuation is not necessarily a verified fact, check important claims against reliable sources.
The activity is a simplified demonstration, not a claim that AI thinks like a person. It helps show one important mechanism behind how ChatGPT generates answers: producing text one token at a time based on patterns and context.
Play “Be the LLM”: Guess what comes next
A token is a small unit of text. It may be a whole word, part of a word, punctuation, or a space combined with text. Models generate a response by repeatedly selecting a likely next token, using the prompt and the text generated so far as context.
Try the game with a friend. Read each prompt aloud and ask them to continue it. Don’t look for a single correct answer. Notice what feels likely, and what information your guess relies on.
The café was busy, so Maya looked for…
Your friend might say “a table,” “a quiet corner,” or “somewhere to sit.” Each continuation fits the sentence, but none is guaranteed. The prompt gives clues about the situation, and your friend uses familiar language patterns to make a plausible guess.
Now try:
The café was busy, so Maya looked for a place to charge…
The new ending makes “her phone” a likely continuation. The prompt narrows the possibilities, but it still doesn’t tell us what Maya actually did.
Maya had been studying for hours and her laptop battery was almost empty. The café was busy, so she looked for a place to charge…
“Her laptop” now seems more likely than “her phone.” The extra information shapes the continuation.
Change one detail:
Maya had been talking to her sister for hours and her phone battery was almost empty. The café was busy, so she looked for a place to charge…
Now “her phone” is the natural guess. This is the point of the round: a small change in context can shift what comes next.
LLMs respond to context in a similar broad sense. Examples and instructions in a prompt can influence the kind of answer a model produces. But a likely continuation is not the same as a verified fact about the world.
What the game reveals about how LLMs generate answers
During training, an LLM processes large collections of text and learns statistical patterns in how words and other tokens appear together. Later, when given a prompt, it generates a sequence of likely continuations. Its answer can reflect patterns learned from training as well as the immediate conversation.
That description is useful, but incomplete: modern systems involve more than a simple word-counting exercise. They are trained and adjusted through multiple stages, and the text they produce can be shaped by instructions and generation settings. Still, next-token prediction offers a helpful mental model for understanding how LLMs produce fluent text.
It does not mean an LLM thinks exactly as a person does. Nor does it mean the model checks every sentence against a reliable source before answering. The game illustrates text generation, not human-like understanding or a built-in fact-checking process.
Why a plausible continuation can turn into a hallucination
A language model is designed to generate a response that fits its input. If a prompt asks for something specific but doesn’t provide the facts needed to answer, the model may still produce a smooth, detailed continuation. When that output includes incorrect or unsupported information, it is often called an AI hallucination.
Jordan met their neighbour at the station. What was the neighbour’s name?
The prompt gives no name. A friend may pause or ask for more information. Someone playing “the LLM” might confidently guess “Sam” or “Alex.” Either answer sounds possible, but neither is supported by the sentence.
Now imagine an AI gives a full name and a story about how the neighbours met. Extra detail can make a response feel more credible, but it doesn’t add evidence. The same caution applies to precise dates, quotations, statistics, legal explanations, and citations: specificity and fluency are not proof of accuracy.
How to use ChatGPT without mistaking fluency for evidence
Use an AI answer as a starting point, especially when the question involves facts that matter. A few habits can lower the risk of relying on unsupported output:
Give context, request sources, and verify important claims: Provide the relevant information. Include the details the model needs, and say when something is unknown. For example: “Use only the information below. If it doesn’t say, tell me that the detail is missing.”, Ask it to separate fact from inference. A useful follow-up is: “Which parts of your answer come directly from my prompt, and which are assumptions?”, Request sources, then check them. A list of citations is not automatically reliable; confirm that each source exists and supports the claim it is attached to., Verify consequential claims independently. Check important medical, financial, legal, safety, or breaking-news information against trustworthy sources or a qualified professional., Treat uncertainty as useful. If the model cannot support an answer, a clear “I don’t know” is better than a confident guess. You can ask it to identify missing information rather than fill in the gaps.
These steps do not guarantee a correct response. They make it easier to spot where an answer depends on assumptions and where you need independent evidence.
A real-world reminder: check AI-generated claims before acting
A 2026 news report described an AI-generated false tip submitted to Philadelphia police. The case is a reminder that people can pass on generated claims as if they were established facts. It does not, by itself, prove exactly how a particular model produced the claim. The practical lesson is simpler: verify serious allegations before sharing them or acting on them.
Try the “Be the LLM” game with a friend, then test the idea with an AI answer. Ask what evidence supports an important claim, and verify that evidence against a reliable source. A plausible continuation can start a conversation; it should not end the fact-check.
Step-by-Step Guide
Play the sentence-completion round
Read “The café was busy, so Maya looked for…” and ask a friend to finish it. Notice that several continuations can fit without any one being guaranteed.
Add context and change one detail
Give the friend information about a nearly empty laptop battery, then change it to a nearly empty phone battery. Compare how the added context shifts the likely continuation.
Test a question with missing information
Ask, “Jordan met their neighbour at the station. What was the neighbour’s name?” Check whether the answer is present in the prompt or is only a guess.
Check an AI answer before relying on it
Ask the model to separate prompt-supported facts from assumptions, request sources, and independently verify important claims against trustworthy evidence.
Key Statistics
- The “Be the LLM” activity is presented in 2 sentence-completion rounds.Counted from the supplied article: one round introduces a sentence, and another adds context and changes a detail. This is an activity-design count, not a research finding.
- The article lists 5 practical habits for checking AI output.Counted from the supplied article’s verification list: provide context, separate facts from inference, check sources, independently verify consequential claims, and treat uncertainty as useful. This is a count of recommendations, not a measured effectiveness statistic.
Frequently Asked Questions
How do large language models generate text?
Why does ChatGPT sometimes make things up?
Does next-token prediction mean an LLM thinks like a person?
How can I check whether a ChatGPT answer is reliable?
Key Takeaways
- The “Be the LLM” game demonstrates how context can influence a likely text continuation.
- Next-token prediction is a useful mental model for LLM output, but it does not capture every part of modern AI systems.
- A model may provide a plausible answer even when the prompt does not contain the facts needed to support it.
- Fluency, specificity, and generated citations do not prove that an answer is accurate.
- For consequential claims, identify assumptions and verify supporting evidence independently.