
LongCat-2.5: Meituan's MIT-Licensed Vision LLM Guide
LongCat-2.5 is Meituan's MIT-licensed vision-enabled LLM. Explore its reported specs, pricing, capabilities, and how to evaluate it for your workflows.
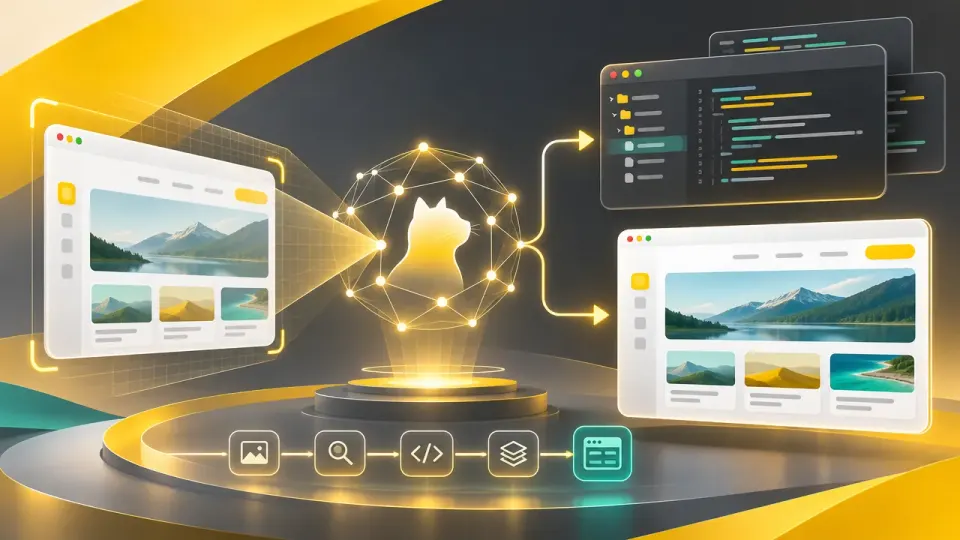
Table of Contents
Quick Answer
Meituan released LongCat-2.5's model weights under the MIT License on November 9, positioning it for visual tasks and extended coding workflows. Developers should verify the release terms, current API pricing, infrastructure needs, and performance on representative tasks before choosing it.
The combination may be useful for teams building tools that need to interpret visual context and act on code. But reported model specifications and API prices should be considered separately from independent evidence of performance: developers will need to test the model against their own workloads.
What Meituan Released on November 9
The release makes LongCat-2.5’s weights available under the MIT License. That license is generally permissive, allowing broad use and modification subject to its terms. For developers, open weights can offer more control over evaluation and deployment than access through an API alone.
The license is one part of the deployment decision, not a substitute for reviewing the complete release materials. Teams should confirm which model files and supporting components are covered, how the weights can be accessed, and what infrastructure is needed to run them. A model’s license also does not by itself establish its suitability for a particular application or the quality of its outputs.
LongCat-2.5 Combines Visual Input With Extended Coding Workflows
Meituan positions LongCat-2.5 for tasks involving visual input and extended software-development work. The model is reported to handle inputs such as screenshots or video, while also working through a codebase rather than responding only to isolated coding prompts.
That pairing suggests several practical evaluation scenarios. A developer tool might ask the model to interpret a screenshot of an interface, locate the relevant component in a repository, and propose a code change. A team could also test whether it can use video frames to understand a user-facing bug, then connect that evidence to the code responsible for the behavior.
These examples describe the kinds of workflows to test, not a guarantee that the model will complete them reliably. Results can depend on the input format, repository size, task complexity, and how the system supplies context. Developers should check performance on representative cases, including tasks where visual details are ambiguous or code changes require multiple steps.
Model Scale, API Pricing, and What Developers Should Check
The reported model scale is 1.6 trillion total parameters, with roughly 48 billion active per token. These figures describe the model’s overall and per-token active parameter counts; they do not, on their own, establish how well it performs or how much compute a particular deployment will require.
Reported API rates are $0.30 per million uncached input tokens, $0.006 per million cached input tokens, and $1.20 per million output tokens. The cited report describes these as limited-time prices. Developers should verify current rates and access terms before estimating costs, and account for how much of a workload can use cached input as well as the volume of generated output.
Meituan’s selected proprietary-model comparisons provide reference points, but they do not independently establish LongCat-2.5’s standing against leading models. A useful assessment should include consistent tasks, comparable settings, and measures that matter to the application - such as code correctness, visual interpretation, latency, and cost.
How to Evaluate LongCat-2.5 Against Your Use Case
Start by checking whether the model’s strengths match the workload. If an application combines screenshots, video, or other visual context with code changes, LongCat-2.5 may merit a focused trial. For text-only coding or general language tasks, compare it with alternatives using the same prompts and evaluation criteria.
Next, decide whether API access or running open weights better fits the team’s needs. API use may simplify initial testing, while self-deployment can offer more operational control but requires suitable infrastructure and maintenance. In either case, assess data handling, response quality, reliability, and total cost using realistic inputs.
Review the model’s license, access options, and current pricing, then test LongCat-2.5 on a representative visual-coding task before choosing it for deployment.
Frequently Asked Questions
What is Meituan's LongCat-2.5?
Is LongCat-2.5 open source?
What can LongCat-2.5 do with visual input and code?
How much does the LongCat-2.5 API cost?
How should developers evaluate LongCat-2.5?
Key Takeaways
- Meituan released LongCat-2.5's weights under the MIT License, which can provide developers broad options for use and modification subject to the license terms.
- The model is positioned to handle visual inputs such as screenshots or video alongside longer software-development workflows.
- Reported specifications list 1.6 trillion total parameters and roughly 48 billion active parameters per token.
- Reported API rates are $0.30 per million uncached input tokens, $0.006 per million cached input tokens, and $1.20 per million output tokens; verify current prices before budgeting.
- Treat vendor-reported specifications and comparisons as starting points, then test the model on representative tasks for quality, latency, reliability, and cost.