AI Agent Token Costs: Why They Add Up and How to Cut Them
AI agent token costs rise with context, model calls, retries, and rates. Learn how to estimate spend per successful task and control it.
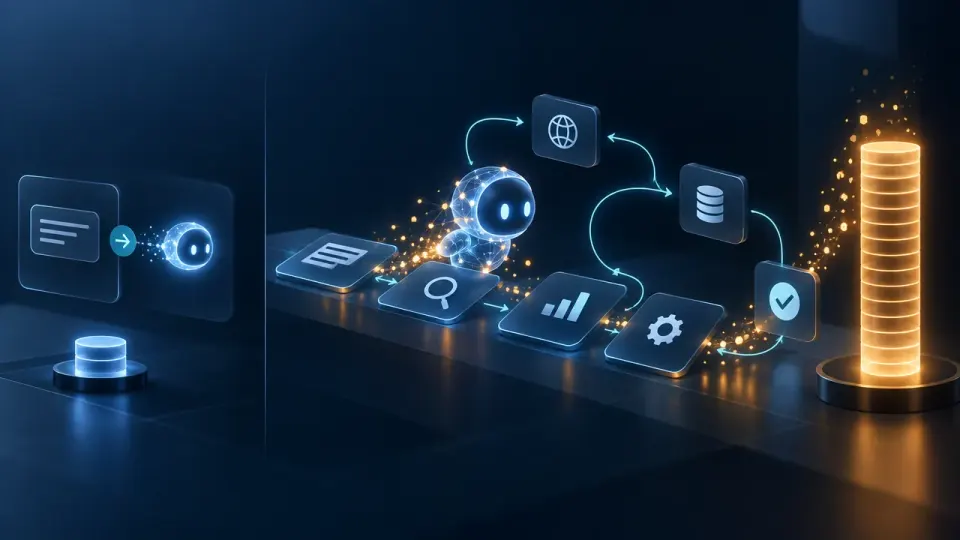
Table of Contents
Quick Answer
AI agents can use more tokens than a single prompt because they may process large contexts, make multiple model calls, use tools, and retry tasks. Estimate costs from input, cached input, output, and other service charges, then track total spend per successful task.
Y Combinator president Garry Tan has reportedly spent up to $200,000 a year on tokens for intensive personal-agent use. That is an example of high-volume use, not a typical cost estimate. For a business or individual, the useful question is what a particular workload costs to complete reliably - and how to keep that cost within a budget.
Why agentic workflows can consume more tokens than a single prompt
A one-off chat usually involves a prompt and a response. An agent may work through a longer sequence: gather context, plan, call a tool, inspect the result, revise its approach, and respond. Depending on the system, it may send some of that context back to the model at multiple stages.
The information being handled matters too. Tan said his agent had read his email, Dropbox files, and years of Apple Notes. Making a large personal or business knowledge base available can require processing a substantial amount of input. The agent may also need to retrieve relevant material and check it as the task progresses.
This does not mean every agent repeatedly sends every file in full. Systems can retrieve selected information or reuse cached inputs. But greater autonomy and ongoing access to information can create more model calls and more tokens than a single prompt. A simple request and a multi-step task that searches records, drafts an answer, and checks its work are not equivalent workloads.
What determines an AI agent's token bill
The main factors are the workload's token volume and the model's rates. Cost can also depend on whether the system processes text, images, audio, or other inputs; how often it calls tools or models; and whether the service charges separately for platform usage or execution.
A basic estimate is:
Estimated model cost = (uncached input tokens × input rate + cached input tokens × cached-input rate + output tokens × output rate) ÷ 1,000,000
Use rates stated per million tokens, and keep each token category separate. For multimodal workloads, check how the provider measures and bills those inputs rather than assuming that an image or audio request maps neatly to ordinary text tokens. Liquid AI's published LFM3 rates, for example, illustrate that model and modality affect token charges. A token calculation is still not a quote for completing a business task: it does not, by itself, capture tool, hosting, or other service charges.
Estimate cost per task, not just cost per token
A low per-token rate does not guarantee a low-cost result. One model may use more tokens, need more calls, or require more corrections than another. Compare the total spend and outcome for the same representative task, not just the headline rate.
A VentureBeat estimate for Gemini 4 Carbon put 10 million uncached input tokens and 1 million billed output tokens at about $30 using introductory rates. The estimate excludes other charges and assumes the token consumption stays unchanged. It is an example of how volume and rates combine, not a price for an agent completing a particular job.
Where possible, calculate cost per successful task : total cost divided by the number of tasks completed to your quality standard. This makes model selection more useful. A pricier model could be the better choice if it completes a task with fewer retries, while a cheaper model may work well for simpler steps.
For example, test both models on the same set of support requests. Track total tokens and cost, then count only the replies that meet your quality criteria. Compare the resulting cost per acceptable reply, not only the cost of one model call.
Industry figures can provide context, but not a universal benchmark. TechCrunch reported that spending on agentic coding tools among Jellyfish's 276,000 customers grew tenfold from the beginning of the year and reached about 2% of total engineering cost. That is a reported finding for that group, not a forecast for every organization. Similarly, Mistral has claimed its ML4 model uses 47% fewer tokens per task than GLM-5.3. Treat that as a company claim to test against your own workload.
Practical ways to control AI agent costs
Salesforce has described controls in Agent Fabric and Model Wallet for tracking usage and managing costs, including budgets and controls that can stop agent activity when needed. The specific features depend on the platform, but the general practice applies broadly: make ownership clear, review usage regularly, and decide in advance what should happen when a limit is reached.
Also trim unnecessary material. Retrieve only the documents needed for the current task, avoid resending redundant instructions or history, and limit response length where a shorter answer will do. These changes can reduce input or output tokens without forcing every task onto a less capable model.
To manage AI agent token costs, begin with a representative workload. Measure its token use, retries, and success rate; calculate the cost using current model rates; then set a budget and review it as usage changes. That gives you a practical baseline without treating any single rate or headline spending figure as the definitive cost of an AI agent.
Step-by-Step Guide
Choose a representative workload
Select a real task, such as responding to support requests, and define the quality standard for a successful result.
Measure tokens and workflow activity
Record input, cached input, and output tokens, along with model calls, tool use, retries, execution time, and task success.
Calculate cost using current rates
Apply the provider's current rates to each token category, then add any platform, tool, hosting, or execution charges that apply.
Compare cost per successful task
Test models on the same workload and divide total workflow cost by the number of results that meet your quality standard.
Set budgets and reduce waste
Assign budgets and alerts to teams or workflows, then trim unnecessary context and use safe caching to reduce repeated processing.
Key Statistics
- Garry Tan has reportedly spent up to $200,000 a year on tokens for intensive personal-agent use.The article presents this as a reported example of high-volume personal-agent use, not a typical cost estimate or a forecast for other users.
- A VentureBeat estimate put 10 million uncached input tokens and 1 million billed output tokens for Gemini 4 Carbon at about $30 using introductory rates.The estimate excludes other charges and assumes token consumption stays unchanged; it illustrates how token volume and rates combine, not the price of completing a specific agent task.
- TechCrunch reported that agentic coding tool spending among Jellyfish's 276,000 customers grew tenfold from the beginning of the year and reached about 2% of total engineering cost.This is a reported finding for the Jellyfish customer group and should not be treated as a universal organizational benchmark.
- Mistral has claimed that its ML4 model uses 47% fewer tokens per task than GLM-5.3.This is a company claim cited in the article; teams should test token use and task quality against their own workloads.
Frequently Asked Questions
Why do AI agents use so many tokens?
How do you calculate AI agent token costs?
What is the best way to compare AI agent costs?
How can businesses reduce AI agent token usage?
Key Takeaways
- Agent costs depend on token volume, model rates, workflow steps, modalities, and any separate platform or execution charges.
- Input, output, and cached input tokens may have different prices, so calculate each category using the provider's current rates.
- Measure representative workflows, including retries and task success, instead of relying only on a per-token price.
- Compare models by cost per successful task and quality, not just by the cost of one model call.
- Control spend with budgets, usage alerts, leaner context, and caching where repeated information can be safely reused.