AI Coding Model Comparison: Benchmarks and Real-World Tests
Compare AI coding models with relevant benchmarks and fair repository tests. Find the right fit for your team's tools, tasks, budget, and privacy needs.
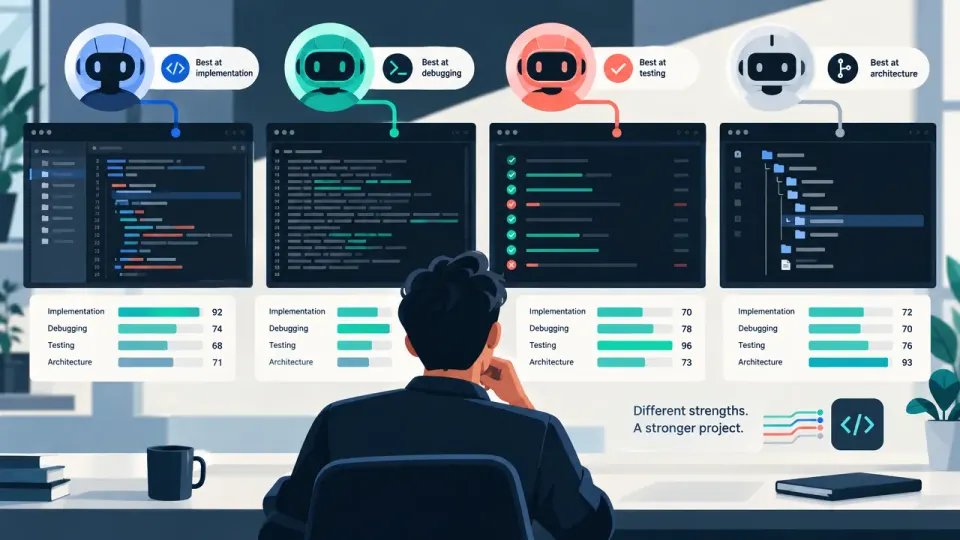
Table of Contents
Quick Answer
Compare AI coding models by using benchmarks that match your work, then testing shortlisted models on representative tasks from your own codebase. Keep tools, instructions, time limits, and evaluation criteria consistent, and measure task success, reliability, code quality, workflow fit, cost, and privacy.
Use benchmarks to narrow your options, then test finalists on representative software tasks under consistent conditions. Compare not just whether a model produces code, but whether it can complete the task reliably within your workflow and operational limits.
Why AI coding model rankings disagree
Even coding tests measure different things. One may reward a correct patch against a fixed issue; another may assess whether an agent can use a terminal to inspect a project, edit files, and run commands. A model can perform well on one test and less well on another because the tasks, tools, and scoring differ.
Treat a headline score as a clue about a model's strengths, not a forecast of how it will perform on your team. An aggregate index is not a substitute for testing your own codebase and development practices.
Before comparing scores, check the benchmark version, date, task set, and evaluation method. Results may not be directly comparable if models used different prompts, agent scaffolding, tools, or test environments. Be especially cautious when a report combines vendor-reported results with independent evaluations, or compares numbers produced under different conditions.
Choose benchmarks that reflect the work you need done
Look for evaluations that describe their task selection, repository setup, test procedure, and success criteria. A passing test is useful evidence, but it may not reveal whether the solution is maintainable, narrowly correct, or free of regressions. Read the evaluation details rather than relying on a score alone.
A terminal score still depends on what the environment permits and how tasks are graded. Check whether the model can use the same tools available in your workflow, and whether the benchmark tests tasks similar to yours. A high result on command-line tasks does not automatically prove strong performance on code review, architecture decisions, or collaboration.
Evaluate tool use separately from code generation
- Navigation: Does it find relevant files without excessive or irrelevant exploration?
- Execution: Can it run the right commands and interpret their output?
- Recovery: Does it respond sensibly when tests fail or a command produces an error?
- Completion: Does it verify the change and report what it did accurately?
Some evaluations measure multi-step activity in broader business processes rather than software engineering. Those results may offer insight into planning and tool use, but they should not be treated as direct evidence of coding ability. Match the benchmark to the capability you want to measure.
Record the model version and configuration, system instructions, tools, and environment. Note whether the model had access to the same files and could run the same tests. This makes results easier to interpret and repeat.
Run a fair comparison on real software tasks
Avoid using only easy, self-contained prompts. Include realistic repository details, while excluding sensitive data unless your evaluation setup is approved for it. If possible, use tasks with known expected outcomes and have a developer review solutions for correctness, readability, and unintended changes.
Run tasks more than once if model outputs vary, and report the range of results rather than selecting only the best attempt. Track completion time and human intervention too. A model that eventually succeeds after extensive correction may be less useful than one with a slightly lower benchmark score that works predictably.
Choose the model that fits your workflow
Compare task success with speed, cost, privacy, deployment options, and integration effort. Consider whether the model can be used with your required editor or agent, whether its data handling meets your policies, and whether its performance is consistent enough for the tasks you want to delegate.
The strongest choice is not necessarily the top-ranked model. It is the one that performs well on your important tasks under the tools and constraints your team will actually use. Start with benchmark results to shortlist candidates, then validate them on your own software work.
Choose a small set of representative tasks from your codebase and run each candidate under the same conditions before deciding which one to adopt.
Step-by-Step Guide
Define the work to evaluate
List the programming tasks you want the model to handle, such as bug fixes, feature changes, test updates, or build failures. Set clear acceptance criteria for each task.
Shortlist models with relevant benchmarks
Select repository-level or terminal-based benchmarks according to your intended workflow. Check each benchmark's version, task set, tools, environment, and scoring method before comparing results.
Prepare representative repository tasks
Choose a small set of realistic tasks from your codebase and provide each candidate with the same starting state and context. Exclude sensitive data unless your evaluation setup is approved for it.
Run candidates under consistent conditions
Use identical instructions, tool access, time or token budgets, and test environments. Record model versions and configurations, and repeat trials when outputs may vary.
Score results and select for workflow fit
Evaluate task success, reliability, code quality, tool use, completion time, and human intervention. Weigh those results alongside cost, privacy, deployment options, and integration needs.
Key Statistics
- The original SWE-bench dataset contains 2,294 software engineering tasks.The SWE-bench paper by Jimenez et al. (2024) describes tasks drawn from 12 Python repositories, with issue-resolution tasks evaluated against repository tests. The figure describes the benchmark dataset, not a model's expected success rate.
- SWE-bench Verified is a 500-task subset of SWE-bench.OpenAI introduced SWE-bench Verified in 2024 as a subset reviewed by human software engineers for clearer, more reliably testable task specifications. Its size is benchmark context, not evidence that any model will perform equally well on a team's codebase.
Frequently Asked Questions
How do you compare AI coding models fairly?
Which benchmarks are useful for comparing AI coding models?
Why do AI coding model rankings disagree?
What should you measure besides code correctness?
Key Takeaways
- Treat benchmark scores as task-specific evidence, not universal rankings of software engineering ability.
- Choose evaluations that reflect the work, such as repository changes or command-line tasks.
- Assess tool use, recovery from errors, and verification separately from code generation.
- Compare models under the same repository, instructions, tools, and time or token budget.
- Use developer review and repeated trials to assess quality, reliability, intervention, speed, and cost.