LLM Critique and Revision: Can AI Models Check Their Work?
Learn how LLM critique and revision works, where AI feedback helps, why it can fail, and how to test safer, evidence-based review workflows.
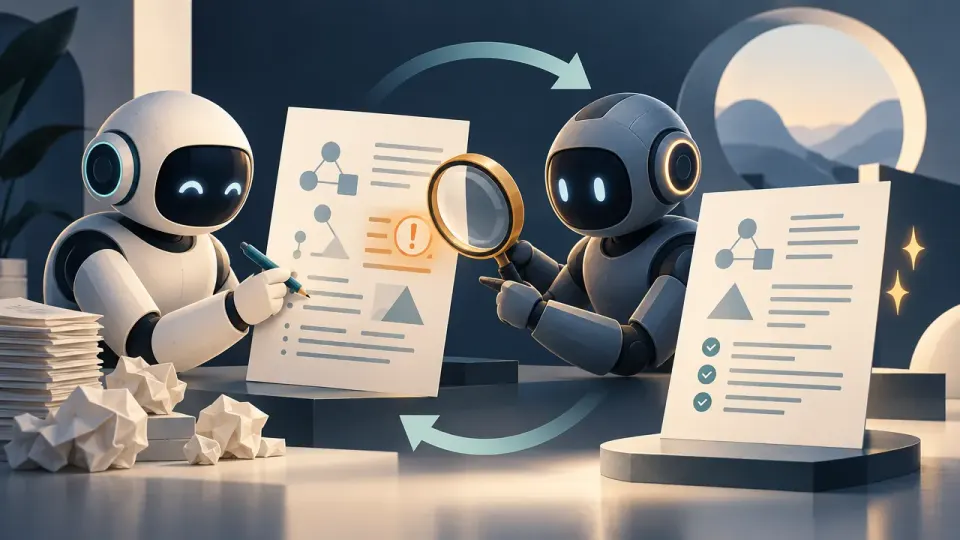
Table of Contents
Quick Answer
LLM critique and revision is a workflow in which a model drafts an answer, checks it against criteria or evidence, and revises it. It can improve outputs on well-defined tasks, but the review does not guarantee correctness, so important claims need independent verification.
This approach can improve an answer when the task has clear requirements and the critique identifies specific problems. But another pass is not proof that the result is correct. A model can miss an error, repeat it, or introduce a new one. Treat critique as a way to improve and inspect output, not as a substitute for evidence or human oversight.
What LLM critique and revision does
The process can repeat, but more rounds do not necessarily mean better results. Each round adds cost and can change correct parts of the answer. In Self-Refine , researchers explored iterative refinement using a model’s own feedback, without additional model training. The work illustrates the method, not a guarantee that it improves every task.
In either case, a critique is only as useful as its basis. “Check your work” gives little direction. “Confirm that every recommendation follows the policy text, and flag any claim the text does not support” gives the reviewer a more testable job.
Four approaches to AI feedback
Principle-guided feedback gives the model written rules to use when reviewing or revising. Constitutional AI, for example, uses a set of principles to guide AI feedback and model behavior. The key distinction is that the critique is anchored to stated values or rules rather than an open-ended request to “make this better.” The principles still need to be relevant, clear, and applied appropriately.
Multi-model debate has multiple models propose or challenge answers, sometimes over several rounds. Research has explored debate as a way to improve factuality and reasoning. Disagreement can surface assumptions worth checking, but consensus is not the same as correctness: models may rely on the same faulty premise or persuade one another toward an unsupported answer.
When critique helps - and why it can fail
The benefit depends on the task and evaluation setup. A revision may improve completeness or style without improving factual accuracy. Decide in advance what “better” means, then measure that outcome rather than relying on the model’s confidence or its claim that it has corrected itself.
An independent reviewer is not automatically independent in practice. Two models may share training data, assumptions, or failure patterns. A confident critique can also sound persuasive while being wrong. For important factual questions, compare claims with a source, calculation, database, or other check that does not simply repeat the model’s judgment.
How to make a critique-and-revision workflow more reliable
Check this answer against the supplied policy. List each claim that conflicts with the policy or lacks support. Do not add new facts. Then revise only the affected parts.
Provide the relevant source material alongside the draft. Where possible, use tools that can independently check specific claims: calculations for arithmetic, tests for code, or a current approved knowledge base for policy details. The model can help interpret results, but the check should not depend solely on the same unsupported generation process.
Evaluate the revised answer before you trust it
A practical checklist:
- Does the revised answer meet the original task requirements?
- Are factual claims supported by evidence outside the model’s critique?
- Did the revision remove correct information or add unsupported details?
- Does the extra step improve a measurable outcome enough to justify its cost and delay?
To decide whether LLM critique and revision belongs in your workflow, choose a representative task, test outputs with and without a critique pass, and compare both against the same criteria and independent evidence. Keep the extra step only if it improves the outcome you care about without creating unacceptable new risks.
Step-by-Step Guide
Define the review criteria
Specify what the reviewer must check, such as factual support, completeness, policy compliance, tone, or whether the answer meets the original request.
Provide the draft and relevant evidence
Give the reviewer the draft and the applicable source material, such as a policy, approved knowledge base, or original document.
Request specific findings
Ask the reviewer to identify claims that conflict with the evidence or lack support, and instruct it not to add new facts.
Revise only the identified issues
Have the model address supported findings while preserving correct information and the requirements of the original task.
Verify and evaluate the result
Check factual claims with independent sources or tools, then compare revised and unrevised outputs against the same task-specific measures.
Escalate consequential decisions
Add qualified human review when mistakes could cause significant harm or affect legal, financial, safety, access, or business outcomes.
Key Statistics
- The Self-Refine study reported an average relative improvement of about 20% across seven diverse tasks compared with the initial outputs.Madaan and colleagues reported this result in their 2023 Self-Refine paper. It reflects the paper's evaluated tasks and setup, not a guaranteed improvement for every model or use case.
- The Reflexion paper reported 91% pass@1 on HumanEval in its evaluated setup.Shinn and colleagues presented this result for a Reflexion agent using verbal feedback and iterative attempts. It is a benchmark-specific finding, not evidence that reflection reliably improves all kinds of reasoning.
Frequently Asked Questions
What is LLM critique and revision?
Can an AI model reliably correct its own reasoning?
How do you make AI critique more reliable?
Is multi-model debate better than self-critique?
When should a human review AI-generated revisions?
Key Takeaways
- A critique-and-revision workflow drafts an answer, evaluates it against explicit criteria, then revises it.
- Specific review instructions and relevant source material make critiques more useful than open-ended requests to check the work.
- Self-critique and multi-model review can share blind spots, repeat errors, or introduce unsupported details.
- Measure revised answers against task-specific criteria and independent evidence, comparing them with outputs that did not receive a critique pass.
- Use human review when errors could affect safety, legal obligations, finances, access to services, or consequential business decisions.