Open-Weight vs Closed AI Models: Which Foundation Fits?
Compare open-weight vs closed AI models across cost, control, privacy, speed, and scalability to choose the right product foundation.
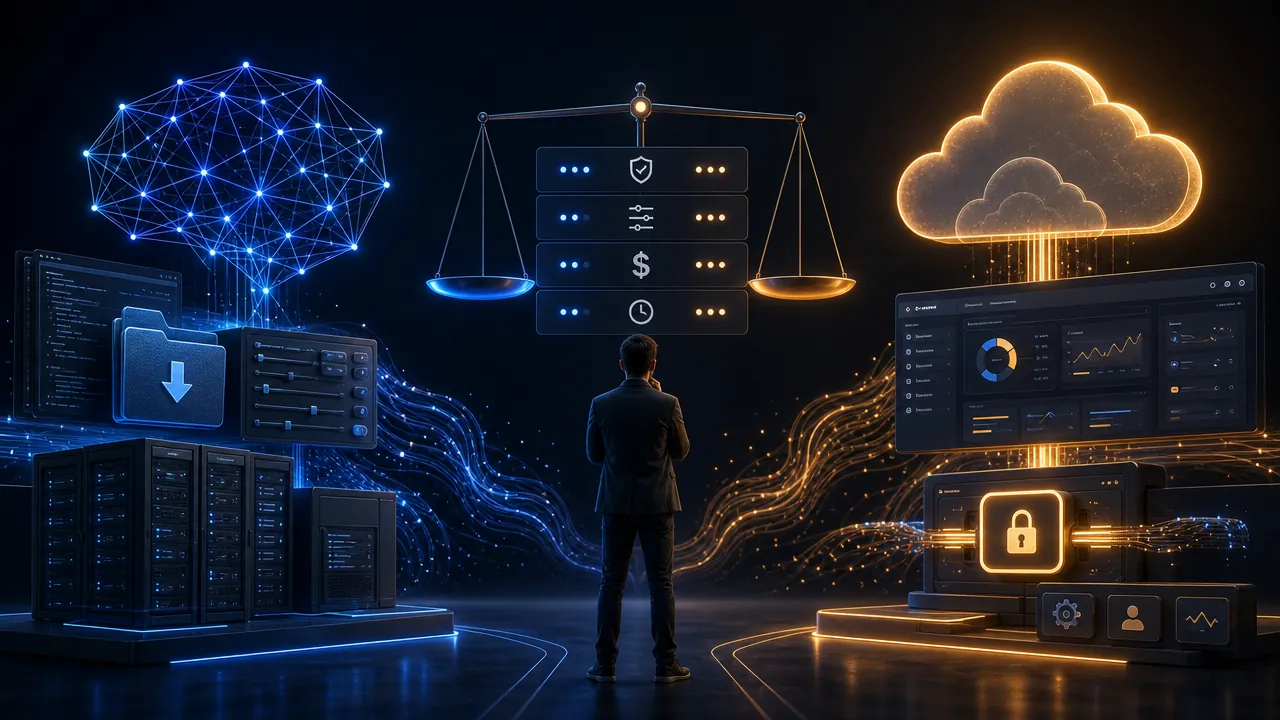
Table of Contents
Quick Answer
Open-weight models offer greater control, customization, privacy, and deployment flexibility, while closed models provide faster access to advanced capabilities through managed APIs. Choose based on workload sensitivity, traffic predictability, latency, customization needs, operational capacity, and tolerance for vendor dependence - and consider a hybrid architecture when requirements vary.
The central question is not whether open-weight or closed models are universally better. It is which approach fits each workload - and whether your architecture allows you to change course as models, prices, regulations, and customer expectations evolve.
Open-weight models can provide deployment control, customization, and greater independence from a single provider. Closed models can provide fast access to advanced capabilities through managed APIs, without requiring your team to operate large-scale inference infrastructure. Many products will benefit from using both.
Open-Weight and Closed AI Models: What Is the Difference?
An open-weight AI model makes its trained parameters, or weights, available for others to download and run under stated licensing terms. The weights encode patterns learned during training. With them, an organization may be able to host the model in its own cloud, data center, or edge environment; adapt it through fine-tuning; and control how requests and outputs are handled.
A closed AI model keeps its weights under the provider's control. Customers generally access the model through an API, hosted application, or managed cloud service. The provider operates the underlying infrastructure and decides when to update, replace, restrict, or retire model versions.
This distinction affects several practical questions:
- Can you run inference without sending data to an external provider?
- Can you fine-tune or modify the model for a specialized domain?
- Can you preserve access if a vendor changes its pricing or policies?
- How much infrastructure and operational expertise must your team provide?
- Who controls model updates, safety behavior, and service availability?
Still, weights create options that a hosted API cannot provide in the same way. An organization can test different quantization methods, optimize latency for a specific hardware target, route sensitive tasks to a private environment, or fine-tune the model on proprietary terminology and workflows.
For example, a healthcare software company might run an open-weight model inside a controlled environment and adapt it to clinical documentation formats. A manufacturing company might deploy a smaller version near factory equipment to reduce latency and avoid depending on a constant internet connection.
An open-weight release may provide model parameters while withholding some combination of:
- Training data or complete data provenance
- Data-cleaning and filtering methods
- Training code and infrastructure details
- Evaluation procedures and safety processes
- The full recipe needed to reproduce the model from scratch
A fully open project aims to expose substantially more of this process, although definitions vary. Before making claims about reproducibility, transparency, or governance, review the license and release documentation carefully. “Open-weight” primarily describes access to the trained model, not complete openness across the entire AI development lifecycle.
The Strategic Trade-Off: Control vs Convenience
The simplest comparison is control versus convenience, but the consequences reach well beyond engineering.
- Local or private deployment: Keep prompts, documents, and outputs within your infrastructure.
- Domain adaptation: Fine-tune or otherwise adapt behavior to specialized language, formats, or processes.
- Predictable availability: Continue serving a supported model version even if a hosted provider changes its catalog.
- Hardware optimization: Select GPUs, accelerators, or edge devices that match your latency and cost targets.
- Sovereign AI requirements: Keep sensitive workloads within a required country, region, or institutional boundary.
Control can also support product differentiation. If every competitor calls the same hosted model with similar prompts, the underlying model may provide limited defensibility. A carefully adapted model, proprietary evaluation system, specialized retrieval pipeline, or optimized deployment stack can become part of a more distinctive product.
The trade-off is responsibility. Your team may need to manage model serving, capacity planning, security patches, observability, abuse prevention, evaluation, and upgrades.
This can compress months of infrastructure work into days of product development. A small team can prototype an AI assistant, automate document analysis, or add voice interaction without purchasing GPUs or building a serving platform.
Managed providers also absorb part of the operational burden. They typically handle capacity, model deployment, baseline monitoring, and infrastructure upgrades. That does not eliminate your responsibility for application safety and reliability, but it can reduce the amount of specialized enterprise AI infrastructure you must build before launch.
Compare Total Cost of Ownership, Not Just Model Prices
A low API price does not guarantee a low-cost product, and an open-weight model is not free simply because its weights can be downloaded.
- Input and output token charges
- Image, audio, or video processing fees
- Peak-demand pricing or reserved capacity
- Retries, tool calls, and multi-step agent workflows
- Data storage and related platform services
For an open-weight deployment, estimate:
- GPU or accelerator acquisition and depreciation
- Cloud instances, networking, storage, and power
- Capacity needed for peak traffic, not only average traffic
- Model loading, batching, quantization, and serving software
- Costs of fallback capacity and disaster recovery
An open-weight model may be cheaper at high, predictable volume because you avoid per-request API margins and can optimize utilization. A closed API may be cheaper for an early product with uncertain demand because you pay for actual usage rather than idle infrastructure.
- Integrate and maintain inference systems
- Tune throughput, latency, and memory use
- Monitor quality, drift, outages, and abuse
- Test new model versions and manage rollback
- Build access controls, audit logs, and data retention policies
- Run red-team exercises and safety evaluations
A closed provider can reduce some of these costs, but not all. Your application still needs input validation, authorization, prompt-injection defenses, output checks, human escalation, and incident response.
Build a five-year scenario model with low, expected, and high usage. Compare not only direct model costs but also launch speed, staffing, downtime exposure, compliance work, and migration expenses.
When Open-Weight Models Are the Better Product Foundation
Local deployment does not automatically make a system private or secure. Your organization still has to secure the servers, restrict administrator access, encrypt data, log usage, and manage model artifacts. But it can reduce exposure to external data processing and give governance teams clearer control over data flows.
Sovereign AI requirements can be broader than privacy. A public-sector organization may need a model that runs on nationally controlled infrastructure, remains available during cross-border disruptions, or can be audited by local authorities. Open-weight deployment may help satisfy those requirements, subject to licensing, hardware, and local operational capability.
Open weights can also support long-term independence. You can preserve a tested model version, maintain your own evaluation suite, and decide when to adopt a newer release. That does not eliminate dependence on hardware suppliers, open-source tooling, or model creators, but it can reduce dependence on one hosted API.
Open-weight is especially attractive when:
- Workloads are high-volume and predictable.
- Latency requirements favor nearby inference.
- Data is highly sensitive or regulated.
- The model needs extensive domain adaptation.
- Offline or intermittent connectivity is necessary.
- A product's differentiation depends on model behavior and deployment.
When Closed AI Models Are the Better Product Foundation
They are also useful when usage is variable. A startup with occasional traffic may spend less on an API than it would on continuously running GPUs. A global company may prefer a provider with established regional capacity, enterprise support, and contractual service commitments.
Closed models are a strong fit when your team prioritizes:
- Rapid prototyping and launch
- Advanced general-purpose reasoning
- Managed scaling and availability
- Minimal model infrastructure ownership
- Access to new capabilities without repeated migrations
That advantage is not permanent. Model quality, pricing, context limits, and service terms can change. Treat a closed model as a replaceable service component, not an unquestioned permanent foundation.
Privacy, Security, Availability, and Vendor Lock-In
With open-weight deployment, sensitive workloads can remain inside a private network. Yet the risk shifts toward your own environment. Poorly secured model endpoints, unrestricted logs, exposed weights, or weak tenant isolation can create serious vulnerabilities.
Reduce lock-in by placing a model abstraction layer between your application and provider-specific APIs. Standardize request and response schemas, maintain workload-specific evaluations, store prompts and configuration in version control, and avoid building core logic around proprietary behavior that cannot be reproduced elsewhere.
Open-weight systems have different continuity risks: hardware shortages, maintainer abandonment, license changes, security vulnerabilities, and difficulty finding engineers with the necessary deployment expertise. Independence is not the same as zero dependency.
Why a Hybrid AI Model Strategy Often Wins
Most products have more than one workload. A single choice can force unnecessary compromises.
Use a closed model for tasks that benefit from frontier capability, such as complex research synthesis, difficult coding, or multimodal interpretation. Use an open-weight model for tasks that require privacy, low latency, predictable high-volume cost, offline operation, or specialized customization.
For example, an enterprise support platform might route:
- Public product questions to a low-cost hosted model
- Confidential account analysis to an internally deployed model
- Difficult escalations to a premium frontier API
- Routine classification to a small open-weight model at high volume
A router can select models based on sensitivity, complexity, latency, geography, and budget. The architecture needs consistent evaluation and fallbacks so that routing does not become an uncontrolled source of quality differences.
How to Evaluate Current Open-Weight Model Options
Treat announcements and vendor performance claims as starting points, not proof. Reported benchmark scores may use different prompts, datasets, evaluators, or hardware. Until released weights and independent evaluations are available, claims about superiority should remain provisional.
Before adopting an open-weight model, verify:
- The weights are actually available, rather than merely planned.
- The license permits commercial use and your intended modifications.
- The model's architecture is compatible with your serving stack.
- Hardware and memory requirements fit your deployment environment.
- Fine-tuning tools and inference optimizations are mature enough.
- Safety behavior is documented and testable.
- The release includes sufficient technical documentation.
Recent market announcements illustrate the spectrum. Mistral has announced a planned open-weight release for its Large 4 model after safety testing, while Reflection has positioned Beam as an open-weight model for enterprise and sovereign AI deployments. Such announcements may be strategically significant, but product teams should wait for the actual release, documentation, licensing terms, and independent testing before making a production commitment.
A Practical Decision Framework for Choosing Your Foundation Model
Measure quality, latency, throughput, uptime, cost per completed task, human review time, and safety failure rates. Then test migration: how difficult would it be to move the same workload to a second model? A model that wins a benchmark but creates major switching costs may not be the best foundation.
Open-Weight vs Closed AI Models: Final Evaluation Checklist
Score each candidate against your actual workloads and business constraints:
Capability and product fit: Does it perform well on representative tasks, not just public benchmarks?, Does it support required text, image, audio, video, reasoning, and tool-use features?, Can it meet your latency, throughput, and context requirements?
Data, safety, and governance: Where are inputs, outputs, and logs processed and retained?, Can you meet privacy, residency, audit, and access-control requirements?, Are safety controls, evaluations, and incident procedures adequate?
Deployment and economics: What infrastructure, skills, and support are required?, What is the five-year total cost at low, expected, and peak usage?, How do inference, monitoring, upgrades, and disaster recovery affect the estimate?
Continuity and flexibility: What happens if the provider changes price, policy, performance, or availability?, If using open weights, who will maintain the deployment and security posture?, Can you switch models without rewriting core product logic?, Are licensing terms compatible with your commercial and geographic plans?
The best foundation is the one that fits the workload and preserves strategic options. Download the AI model selection checklist and score your leading open-weight, closed, and hybrid options against actual workloads, data requirements, infrastructure, and five-year total cost of ownership.
Step-by-Step Guide
Classify your workload requirements
Document data sensitivity, residency rules, latency targets, connectivity constraints, volume patterns, multimodal needs, and customization requirements for each AI feature.
Compare model capabilities
Evaluate representative open-weight and closed models using the same task-specific dataset, measuring quality, context handling, tool use, safety behavior, latency, and reliability.
Calculate total cost of ownership
Model low, expected, and high usage over five years, including API fees, GPU capacity, staffing, observability, security, compliance, downtime, disaster recovery, and migration costs.
Assess operational and governance capacity
Confirm whether your team can manage serving, scaling, patching, access controls, evaluations, abuse prevention, incident response, and model upgrades for a self-hosted deployment.
Design for provider and model portability
Separate application logic from model-specific APIs, create evaluation benchmarks, standardize prompts and outputs, and maintain routing or fallback options where practical.
Pilot the highest-risk workload first
Run a controlled proof of concept with representative data and production-like traffic, then validate quality, privacy, cost, latency, availability, and rollback procedures before committing.
Key Statistics
- The NIST AI Risk Management Framework is a voluntary framework for managing AI risks across the functions Govern, Map, Measure, and Manage.The U.S. National Institute of Standards and Technology published AI RMF 1.0 in January 2023; it provides a governance reference for evaluating either self-hosted or managed models.
- The EU AI Act entered into force on August 1, 2024, with obligations applying on a phased timeline.The European Union's official AI Act timeline makes regulatory readiness, documentation, risk management, and deployment geography relevant to foundation-model selection.
- The EU AI Act's general-purpose AI obligations began applying on August 2, 2025, with some related enforcement and harmonized-standard milestones extending beyond that date.This phased schedule is documented by the European Commission and illustrates why model providers, licenses, documentation, and governance processes should be reviewed before adoption.
Frequently Asked Questions
What is the difference between open-weight and closed AI models?
Are open-weight AI models cheaper than closed models?
When should a company choose an open-weight model?
When are closed AI models the better choice?
Can a product use both open-weight and closed AI models?
Key Takeaways
- Open-weight models provide control over deployment, customization, model versions, hardware optimization, and sensitive data flows.
- Closed models reduce infrastructure ownership and can accelerate product launches with managed access to advanced capabilities.
- Total cost of ownership includes API or GPU costs, engineering, monitoring, security, compliance, upgrades, downtime, and migration risk.
- Open-weight models are strongest for sensitive, high-volume, latency-critical, offline, regulated, or deeply specialized workloads.
- Closed models are strongest for rapid experimentation, variable demand, small infrastructure teams, and fast-changing multimodal capabilities.