
LLM Complex Question Evaluation: Test Reasoning & Accuracy
Learn how to evaluate LLMs on complex, multi-part questions by scoring reasoning, ambiguity, instruction following, cost, and real-world performance.
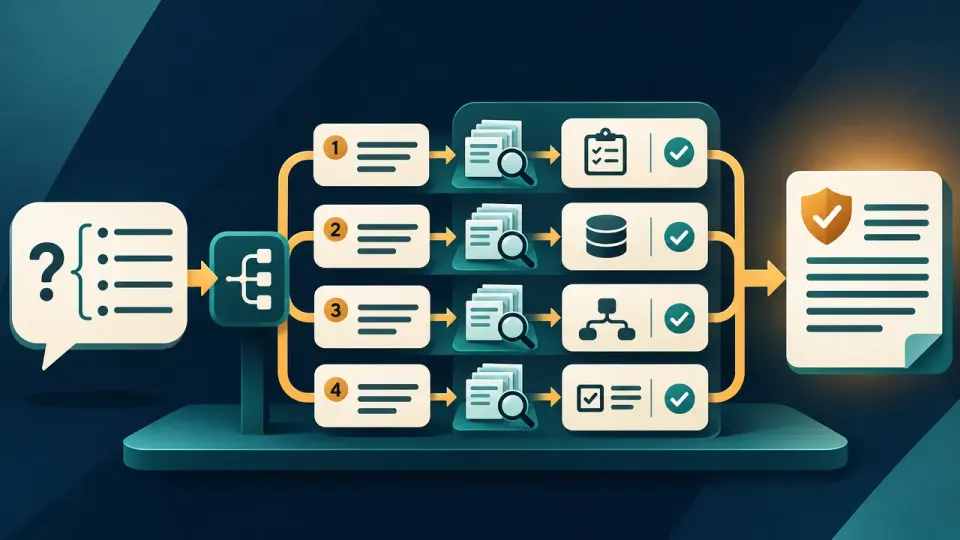
Table of Contents
Quick Answer
Evaluate LLMs on complex, multi-part questions by scoring each requested component separately for completeness, factual correctness, reasoning, ambiguity handling, and instruction compliance. Use realistic test prompts, compare models under matched conditions, and monitor quality, cost, and latency in production.
Why One Accuracy Score Can Mislead
An overall score compresses different capabilities into one number. A model might get the main fact right but omit a caveat, ignore a formatting constraint, or make an unsupported inference. Those failures have different causes and need different fixes.
Reported experience from PayPal illustrates how much evaluation conditions can matter: the company said an AI assistant's accuracy rose from 43% to 95% without changing the model, attributing the difference to testing and production conditions. The takeaway is not that every low score is a testing problem. It is that results depend on what is tested and how closely the test resembles the real task.
Treat an LLM complex question evaluation as a diagnostic, not just a leaderboard. The useful question is not only “How often was the answer correct?” but also “Which parts failed, and under what conditions?”
Build a Test Set That Reflects Real User Questions
Start with examples from the product's intended use: user-submitted questions, support logs, or realistic drafts from domain experts. Remove personal or sensitive information, then categorize the prompts by task, risk, and complexity.
Include frequent requests, but also less common questions where an error could have a high cost. For example, a benefits assistant might receive routine questions about eligibility as well as less frequent questions about deadlines, exceptions, or what documents to submit. A test set made mostly of easy, common prompts could make the system look stronger than it is on consequential cases.
For each example, document the expected answer or the criteria a good answer must meet. When a prompt has multiple valid responses, score against those criteria instead of insisting on one exact string. Keep a held-out set that is not used to tune prompts or model settings; otherwise, results may reflect familiarity with the test rather than general performance.
Score Each Part of the Answer Separately
Break each multi-part prompt into explicit requirements. Consider this question:
“Summarize the incident, identify the likely cause, recommend two next steps, and state what information is still missing.”
Score each requested component individually. A simple rubric might track:
- Completeness: Was every requested part addressed?
- Factual correctness: Are claims supported by the provided information?
- Dependency handling: Does the recommendation follow from the summary and likely cause?
- Unsupported claims: Did the model invent details or present a guess as fact?
- Instruction compliance: Did it provide exactly two next steps and identify missing information?
Keep completeness separate from correctness. A response can be accurate but incomplete, or complete in structure but wrong in substance. Record a pass or score for each requirement, then report the overall result alongside component-level rates. If a model scores well overall but repeatedly fails to mention missing information, that pattern should be visible.
Use human reviewers for nuanced cases, with clear scoring guidance and a process for resolving disagreements. Automated graders can help with scale, but validate them against human judgments, especially for subjective or high-stakes questions.
Test Reasoning, Ambiguity, and Instruction Following
A useful multi-part question benchmark includes more than straightforward fact retrieval. Add prompts that require connecting evidence, handling missing information, and recognizing when the question has more than one reasonable interpretation.
For an ambiguous prompt, the best response may be a clarifying question, a clearly stated assumption, or an answer that explains the possible interpretations. Score whether the model handled uncertainty appropriately, not whether it guessed the interpretation you expected. For example, if a user asks, “Can I submit this late?” without naming a policy or deadline, a confident yes or no should not receive full credit unless the needed context is available.
Test the LLM instruction following test separately from answer quality. Vary requirements for format, scope, tone, and steps: “Answer in three bullets,” “use only the supplied policy,” or “list the assumptions before recommending an action.” Track each constraint as met or missed. This makes it easier to distinguish a reasoning weakness from a prompt or formatting failure.
Simulate Multi-Turn Use and Compare Models Fairly
Many real tasks unfold over multiple messages. Test whether the model retains relevant details, applies corrections, and asks for clarification when new information changes the answer. Include cases where a user revises a requirement or provides a key fact late in the conversation. This is a practical form of multi-turn LLM testing that single-prompt benchmarks miss.
You can also use synthetic questions to expand coverage, but review them before treating them as ground truth. They may repeat the same pattern, contain incorrect assumptions, or fail to reflect how people actually ask for help. PayPal has described using synthetic question generation and multi-turn testing as part of its evaluation approach, underscoring the value of testing beyond a static set of prompts.
When comparing models, keep conditions matched: use the same question set, system instructions, tools, context, and output budget. Record model versions and settings. Report results by task type as well as in aggregate. Benchmark results only describe the particular tasks and versions tested; reported comparisons between model versions, such as Meituan's LongCat releases, are most useful when tied to those specifics.
Track Production Gaps, Cost, and Latency
An offline score is not a guarantee of production performance. Real users may phrase questions differently, omit context, or create longer conversations than your test set. Compare live outcomes with evaluation results, review failures, and add representative cases to the next test cycle. Keep a stable set for tracking changes and a separate set that grows as new failure modes appear.
The gap can be substantial: in a VB Pulse survey, 42% of respondents whose organizations conducted pre-deployment evaluations said an AI agent or LLM feature had passed internal tests but later failed. Among respondents reporting failures, 49% said the most significant incident reached customers. These figures make a case for monitoring after launch, not for abandoning pre-deployment testing.
Track practical measures alongside quality: cost per completed task, response time, tool use, and escalation or clarification rates. If you use multiple models or a synthesis layer, check that the final answer selects the best-supported response rather than merely blending conflicting claims. Compare quality, latency, and cost under the same workload.
Evaluation should continue as models and use patterns change. Include fresh prompts, monitor for shifts in behavior, and avoid relying solely on a public benchmark or a familiar test set. A model may behave differently when it recognizes an evaluation, so varied, realistic tests and production monitoring matter.
Start with a small, representative evaluation set for your highest-impact multi-part questions. Score each requested component, test ambiguity and instruction following independently, and record cost and latency before deploying or changing a model.
Step-by-Step Guide
Build a representative question set
Collect realistic prompts from intended use cases or domain experts, remove sensitive information, and label questions by task, complexity, and risk. Include common requests and less frequent high-impact cases.
Define component-level scoring criteria
Break each prompt into explicit requirements and define how to score completeness, factual support, reasoning, uncertainty handling, and instruction compliance. Use criteria rather than exact-string matching when multiple answers can be valid.
Test ambiguity and instructions separately
Create cases with missing context or multiple plausible interpretations, then check whether the model asks for clarification or states its assumptions. Vary format, scope, tone, and source constraints to measure instruction compliance.
Run multi-turn and matched model tests
Test revised requirements, late-arriving facts, and correction handling across multiple messages. Compare models using the same prompts, instructions, tools, context, output budget, and recorded model settings.
Monitor production outcomes and operating costs
Compare live failures with offline results, add representative failure cases to future test cycles, and track quality alongside cost per task, latency, tool use, and clarification or escalation rates.
Key Statistics
- PayPal reported that an AI assistant's accuracy rose from 43% to 95% without changing the model.The article attributes the increase to differences in testing and production conditions, as described by PayPal. The figures illustrate how evaluation setup can affect reported performance; they are not a general benchmark for all models.
- 42% of respondents whose organizations conducted pre-deployment evaluations said an AI agent or LLM feature passed internal tests but later failed.This figure comes from a VB Pulse survey cited in the article. It supports monitoring after launch in addition to pre-deployment testing.
- Among respondents reporting those failures, 49% said the most significant incident reached customers.This is another finding from the VB Pulse survey cited in the article, and applies to respondents reporting failures. It highlights the potential customer impact of production gaps.
Frequently Asked Questions
How do you evaluate an LLM on complex, multi-part questions?
Why is one accuracy score not enough for LLM evaluation?
How should an LLM handle ambiguous questions during testing?
How do you test LLM instruction following?
What should teams monitor after deploying an LLM?
Key Takeaways
- A single accuracy score can conceal omissions, unsupported claims, reasoning errors, and instruction-following failures.
- Build evaluation sets from realistic user questions, include high-risk edge cases, and keep a held-out set for unbiased measurement.
- Score each part of a multi-part answer independently, separating completeness from factual correctness.
- Test ambiguity, missing information, format constraints, and multi-turn changes as distinct evaluation conditions.
- Compare models under matched settings and track production quality, cost, latency, and failure patterns.