
Box NVIDIA Nemotron: Agent-First Content Retrieval
Box NVIDIA Nemotron powers Box's agent-first content retrieval system. See how it finds document passages and what the early-2027 rollout means.
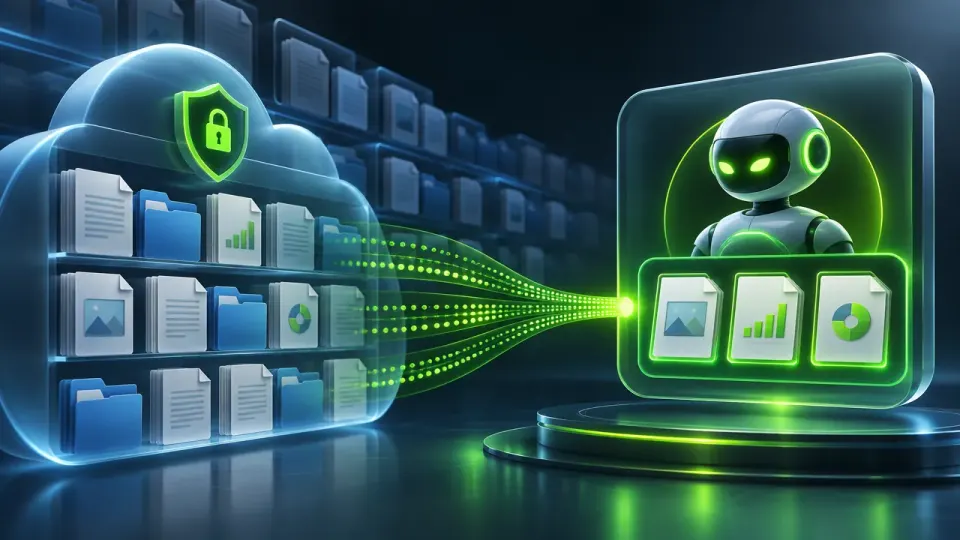
Table of Contents
Quick Answer
Box Content Retrieval uses NVIDIA Nemotron embeddings to help AI agents find relevant passages in enterprise documents instead of processing entire files. Box expects the system to roll out to Enterprise Advance customers in early 2027, but its performance claims have not been independently verified.
The announcement points to a practical shift in how companies prepare content for AI agents. Rather than asking an agent to open documents one by one and read them in full, Box aims to provide a retrieval layer that identifies useful passages for a query. That could reduce the amount of information an agent needs to handle while helping it focus on the content most relevant to a task.
How Nemotron Embeddings Help Agents Find Relevant Content
Embeddings represent content in a form that systems can use to identify relationships and relevance. Box Content Retrieval uses NVIDIA Nemotron embeddings to create metadata for document content. When an agent makes a request, the system can use that information to locate relevant chunks of documents and return them for use.
This approach differs from simply handing an agent a large collection of files. A company’s content may include long documents with only a few passages that answer a particular question. Retrieving those sections can make the interaction more targeted and avoid spending time and computing resources on unrelated material.
For businesses building AI workflows, retrieval is an important part of connecting agents to company information. The agent still needs to interpret the returned material and complete its task, but it may not need to ingest every document from beginning to end. Box is positioning its product as infrastructure for that content-access step.
Box's Expected Speed, Accuracy and Token Savings
Box and NVIDIA have shared performance expectations for the system, but the figures should be understood as reported claims rather than independently verified results. NVIDIA vice president of generative AI software Kari Briski said queries are expected to be four times faster, with 20% fewer errors and 90% fewer tokens used.
The token estimate is particularly relevant to agent-based workflows, where a system may repeatedly retrieve and process information across multiple steps. Using fewer tokens could reduce the amount of content an agent has to process. Faster queries and fewer errors would also matter for tasks that depend on retrieving the right information quickly. Actual performance will depend on how the product works in practice and the content and workflows customers use.
Rollout Timing and the Race to Build Agent-Ready Platforms
Box Content Retrieval is expected to roll out early in 2027 to Enterprise Advance customers. The announcement describes a planned release, so availability and real-world performance remain ahead. Box has not yet detailed the full rollout process in the reported announcement.
The move reflects a wider push to build infrastructure that makes business content usable by AI agents. Dropbox, for example, is developing DBX Agent Cloud, a storage platform for businesses and developers building AI models and agents, with plans to support multiple content types. The efforts take different approaches, but both show how content platforms are adapting to systems that need structured access to information, not just a place to store files.
For Box customers, the key test will be whether retrieval can make agents more useful without sacrificing the relevance and reliability of the information they return. Follow Box’s product updates for details on the expected early-2027 rollout to Enterprise Advance customers.
Frequently Asked Questions
What is Box Content Retrieval?
How does NVIDIA Nemotron help Box retrieve content?
When will Box Content Retrieval be available?
How much faster is Box Content Retrieval expected to be?
Key Takeaways
- Box Content Retrieval is designed to help AI agents locate relevant sections of enterprise documents.
- The system uses NVIDIA Nemotron embeddings to create metadata that supports retrieval of document chunks.
- Box and NVIDIA report expected improvements of four times faster queries, 20% fewer errors, and 90% fewer tokens used.
- The performance figures are reported expectations, not independently verified results.
- The planned rollout is early 2027 for Box Enterprise Advance customers.